Here is something I find oddly reassuring: a lot of IT outages are not caused by attackers or dying hardware. They start with a routine change made with good intentions and no safety net, which is exactly the gap IT change management closes. The July 2024 CrowdStrike incident is the extreme version. According to Microsoft in 2024, one faulty update affected about 8.5 million Windows devices.
You probably are not shipping security software to millions of machines. But you are patching servers, editing email routing rules, adding integrations, and maybe moving off a ticketing system that is being sunset. I don’t think small teams lack discipline. I think most change management advice is written for large enterprises with weekly review boards, so lean teams either copy a process that collapses under its own weight or skip the process entirely.
This guide takes the middle road. You will learn what IT change management is, how ITIL treats it in 2026, and an 8-step process you can set up without new headcount. I have included a filled-in change request, a risk scoring table, and the few metrics worth tracking.
What Is IT Change Management?
IT change management is a structured way to control additions, modifications, and removals to anything that affects an IT service, such as servers, software, network settings, access permissions, and integrations. It makes sure each change is recorded, its risk is checked, the right person approves it, and someone confirms it worked afterward.
IT support teams, internal service desks, managed service providers, and DevOps teams all use it. It is one of the core practices of IT service management (ITSM), and you will also see it called IT change control or, in ITIL 4, change enablement. In this guide, all three terms mean the same thing.
It is not the same as organizational change management, which helps people adapt to new ways of working. IT change management governs the systems. I compare the two in more detail further down.
What Counts as an IT Change?
A change is anything you add, modify, or remove that could affect a service people depend on. Common examples include:
- Installing operating system patches, firmware updates, or new software versions
- Editing firewall rules, DNS records, VPN settings, or email forwarding and routing rules
- Adding, removing, or reconfiguring integrations between systems
- Changing security groups or access permissions for many users at once
- Migrating a system, such as moving from a server-based ticketing tool to a cloud help desk
- Editing automation in your own help desk, such as assignment or follow-up rules
Resetting one user’s password or setting up a new laptop from a known image is usually a service request, not a change. If that line feels blurry, this breakdown of incidents vs. service requests helps.
Why Do IT Changes Need Control?
IT changes need control because unplanned or poorly tested changes are a leading source of preventable downtime. A light process catches risky changes before they reach users, gives you a fast way to roll back, and leaves a record that makes troubleshooting and audits far easier.
The cost of getting it wrong keeps rising. A study by Uptime Institute in 2026, drawing on its 2025 survey data, found that 57% of respondents said their most recent major outage cost more than $100,000. For the second year in a row, about 1 in 5 put the cost above $1 million.
The same research names failure to follow established procedures as the leading driver of outages caused by human error. Andy Lawrence, executive director of Uptime Intelligence, put it plainly: “further resiliency gains are becoming harder to achieve.” Process discipline is one of the few gains still within a small team’s control.
Here is what changes in practice when you put a process in place:
- For employees and customers: Fewer surprise outages, and advance notice when downtime is planned.
- For your IT team: Less firefighting, because you can see the last five changes made to a broken system in seconds.
- For leadership and auditors: A change log that shows who requested, approved, and made each change. Internal auditors treat change management as a core IT general control, as the IIA’s audit guide on IT change management explains.
Ignoring it rarely causes a crisis on day one. It causes slow damage: knowledge that lives in one person’s head, outages nobody can trace, and audit requests that take days to answer.
What Are the 3 Change Types?
ITIL groups IT changes into three types. Standard changes are low-risk, repeatable, and pre-approved. Normal changes need a risk assessment and approval each time. Emergency changes must happen right away to fix or prevent a serious incident, so they follow a faster, smaller approval path and get reviewed afterward.
Standard Changes
Standard changes are routine tasks you have done many times with a known outcome, such as deploying a tested printer driver or adding a user to a shared mailbox. You approve the procedure once, then run it without asking every time.
Normal Changes
Normal changes are everything that is not pre-approved and not urgent. Upgrading a database, changing email routing, or migrating a system all qualify. They need a risk score, an approver, and a schedule.
Emergency Changes
Emergency changes fix something that is broken or about to break, such as patching an actively exploited vulnerability. One or two named people approve them quickly, and every emergency change gets a review after the fact.
| Change type | Risk | Approval needed | Example | Small-team approver |
| Standard | Low, well understood | Pre-approved once | Monthly workstation patches after a pilot | None per change |
| Normal | Low to high | Every time, scaled to risk | Migrating the support mailbox to a new help desk | Team lead or IT manager |
| Emergency | High urgency | Fast, then reviewed | Patching a vulnerability under active attack | IT manager or on-call lead |
How Does Change Control Work?
IT change control works as a lifecycle with six stages: a change is requested, assessed for risk, authorized by the right person, scheduled, implemented with a rollback plan, and reviewed before it is closed. Each stage leaves a record, so anyone can see where a change stands and why it was approved.
The IT change management lifecycle looks like this:
- Request: Someone submits a request for change (RFC) describing what, why, and when.
- Assess: The change owner scores risk and impact and checks for conflicts with other work.
- Authorize: The change authority approves, rejects, or asks for more detail.
- Schedule: The change goes on the change calendar and affected users are told.
- Implement: The team makes the change, tests it, and rolls back if success criteria are not met.
- Review and close: The team confirms the outcome, records lessons, and closes the record.
Inputs usually come from incident fixes, vendor advisories, user requests, or projects. Outputs are an updated system, a complete change record, and sometimes a new standard change you can reuse.
Who Is Involved?
| Role | What the role does | Small-team version |
| Change requester | Asks for the change and explains the business reason | Anyone: a technician, department head, or vendor |
| Change owner | Plans, implements, and documents the change | Usually the technician doing the work |
| Change authority | Approves or rejects the change based on risk | Team lead for low risk, IT manager for medium, IT manager plus business owner for high |
| Change Advisory Board (CAB) | Reviews high-risk or cross-team changes as a group | A 15-minute call or a ticket thread with two or three people, only when needed |
| Change manager | Owns the process and its metrics | Often the IT manager, part time |
FREE. All Features. FOREVER!
Try our Forever FREE account with all premium features!
How Do You Set Up the Process?
To set up an IT change management process, define what counts as a change, sort changes into standard, normal, and emergency types, create one intake form, score risk, assign approvers by risk level, schedule and communicate, implement with a backout plan, and review every change before closing it.
Before you start, have three things ready: a list of the systems your organization cannot work without, the ticketing tool your team already uses, and agreement from your manager on who approves what. Then work through these IT change management process steps in order.
Step 1: Write a One-Page Change Policy
Define what counts as a change in your environment and which systems are critical. Keep it to one page so people actually read it.
- List your top 10 to 15 critical systems, such as email, identity and single sign-on, payroll, the clinical or ERP platform, and your help desk.
- State that any change to those systems needs a change record.
- Name the approvers for each risk level (Step 5 covers how).
Practical tip:If you are unsure whether something counts, ask: “Could this stop someone from doing their job if it goes wrong?” If yes, it is a change.
Step 2: Sort Changes Into Three Types
Use the standard, normal, and emergency types from earlier. The work here is building your first standard change catalog.
- Start with five to ten routine, low-risk tasks your team repeats every week or month.
- For each one, write the exact steps, the expected result, and how to undo it.
- Approve each procedure once, then let technicians run it without a new approval.
Practical tip:A useful rule of thumb is to promote a normal change to standard after it has succeeded several times with no incidents. Revisit the list every quarter.
Step 3: Create One Change Request Intake
Every change should enter through one door, not through chat, hallway conversations, or personal email. Set up a dedicated change request form or ticket type with required fields.
- Required fields: title, change type, reason, systems affected, users affected, risk score, implementation window, backout plan, and approver.
- Routing: Send all requests to one queue so nothing gets lost.
- Labels: Tag each request as Standard, Normal, or Emergency so you can filter and report on it.
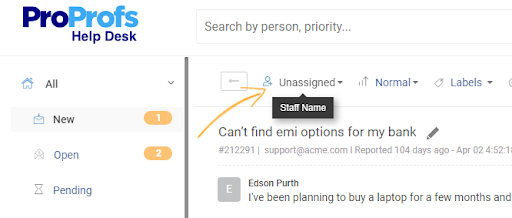
A custom ticket form with these fields makes the request complete before anyone reviews it. You will see a filled-in example in the next section.
Step 4: Score Risk and Impact
Risk scoring decides how much scrutiny a change gets. Keep it to three questions so it takes under a minute.
| Question | Score 1 | Score 2 | Score 3 |
| How many people are affected? | One team or fewer than 10 people | One department or site | The whole organization or external customers |
| How easy is it to undo? | Tested rollback in minutes | Rollback possible but untested | No clean rollback |
| Have we done this before? | Yes, successfully | Only in a test environment | First time |
Add the three scores. A total of 3 to 4 is low risk, 5 to 7 is medium, and 8 to 9 is high. Also check the change calendar for conflicts, such as two changes touching the same system on the same night.
Step 5: Assign the Right Change Authority
Match the approver to the risk score instead of sending everything to a weekly meeting.
- Low risk (3 to 4): A peer or team lead approves in the ticket, ideally the same day.
- Medium risk (5 to 7): The IT manager approves.
- High risk (8 to 9): The IT manager and the affected business owner approve together. This is your CAB, and it can happen in a ticket thread.
One rule matters more than the rest: the person making a normal change should not be its only approver. If you are a one-person IT team, have the business owner approve high-risk changes in writing and keep your backout plan attached to the record.
Step 6: Schedule and Communicate the Change
Put every approved change on a shared change calendar and pick a window when the fewest people will notice.
- Set change freeze periods around business-critical dates, such as payroll runs, month-end close, open enrollment, or peak sales weeks.
- Notify affected users ahead of time with the date, expected impact, and who to contact.
- Send a short “done” message when the change is complete.
A simple notice works: “On Saturday from 8 to 11 a.m., the IT support inbox will move to a new system. Emails sent during that time will still arrive. Questions? Reply to this message.”
Step 7: Implement With a Tested Backout Plan
Follow the approved steps, and write down anything that differs from the plan as you go.
- Define success criteria before you start, such as “test emails from both company domains create tickets in the right queue.”
- Set a rollback trigger, such as “if success criteria are not met within 30 minutes, roll back.”
- Split large changes into subtasks owned by different people, and keep internal notes on the record.
Parent and child tickets with private notes are a practical way to track subtasks across teams without a separate project tool.
Step 8: Review, Close, and Improve
Close a change only after you confirm it worked and nothing else broke.
- Record the outcome: successful, successful with issues, rolled back, or failed.
- Link the change to any incident it caused, so patterns become visible over time.
- Review every emergency change within a few business days and decide whether it reveals a planning gap.
- Update your runbooks and add the change to the standard catalog if it is now routine.
This is also where change management meets incident management: when an incident starts, the first question should be “what changed recently?”
What Does a Good RFC Look Like?
A good request for change (RFC) answers six questions in plain language: what is changing, why, who and what it affects, how risky it is, how you will undo it, and who approved it. If a reviewer cannot understand it in two minutes, it needs rewriting.
Here is a sample built around a change many small IT teams face right now: moving off a ticketing system that is being sunset. If you are planning that move, this guide to help desk migration covers the data side in more depth.
| Field | Example entry |
| Title | Move IT support intake from legacy on-premises ticketing server to cloud help desk |
| Change type | Normal |
| Requester | IT systems support engineer |
| Change owner | Same engineer, with the help desk admin for subtasks |
| Reason | Vendor is sunsetting the current tool; the server also needs ongoing maintenance |
| Systems affected | IT support mailbox, email forwarding rules, single sign-on, ticket categories |
| Users affected | About 250 employees across two related companies that share one IT desk |
| Risk score | Users 3 + Rollback 2 + Experience 3 = 8 (High) |
| Test plan | One-week pilot with the IT team only, then a 3-day parallel run |
| Implementation window | Saturday, 8 to 11 a.m. |
| Backout plan | Re-point forwarding to the legacy server, which stays read-only for 30 days |
| Success criteria | Test emails from both company domains become tickets in the correct team queue within 2 minutes |
| Communication | Email to all staff 5 business days before and again on the day |
| Approvers | IT manager and operations director |
| Review date | The following Wednesday |
Notice what the example does well. The risk score explains why two approvers are involved. The backout plan names a specific action, not “we will fix it if it breaks.” The success criteria are testable in minutes.
What Problems Does It Solve?
IT change management solves the everyday problems that come from changes being made informally: lost change history, unclear accountability, surprise downtime, slow audits, and the same failed change happening twice.
| Problem | How change management addresses it | Practical result |
| Changes logged in chat or personal email and lost | One change record per change in a single queue | Any change history is searchable in seconds |
| “Who changed this?” after an outage | Requester, implementer, approver, and timestamps on every record | Faster root cause analysis |
| The same person requests and approves | A separate change authority for normal changes | A second set of eyes catches blind spots |
| Patches wait days for a meeting | A pre-approved standard change catalog | Routine work keeps moving |
| Users surprised by downtime | A change calendar and advance notices | Fewer “is the system down?” tickets |
| Audit requests take days | An exportable change log with approvals attached | Evidence ready in minutes |
| A failed change gets repeated | Post-implementation reviews and linked incidents | Lessons turn into updated runbooks |
How Does ITIL Handle Change?
ITIL treats change as a management practice called change enablement. Its purpose is to maximize the number of successful changes by assessing risk, authorizing changes, and managing the change schedule. Earlier versions called it change management (ITIL v3) and change control (early ITIL 4). ITIL (Version 5), introduced in early 2026, keeps it as a core practice.
If you are new to the framework, this primer on what ITIL is explains the basics. For change management in ITIL, three ideas matter most.
What Changed in ITIL 4?
- Practice, not just a process: ITIL 4 describes change enablement as a practice that spans the whole service value chain, not a single fixed workflow.
- Change authority instead of an all-purpose CAB: Approval goes to whoever is right for that type and risk of change, which can be a person, a group, or an automated check.
- Automation for low-risk work: ITIL 4 encourages pre-approved and automated paths for standard changes, as this overview of change enablement from ITSM.tools explains.
Does ITIL (Version 5) Change Anything?
PeopleCert announced ITIL (Version 5) in January 2026, and the Foundation certification became available in February 2026. According to PeopleCert’s overview, the update focuses on complex, AI-enabled environments. Change enablement now sits in a Plan, Implement and Control module alongside release, deployment, configuration, and IT asset management.
For a small team, the practical takeaway is reassuring. Nothing in this guide needs rewriting. The direction of travel is the same: risk-based approval, more automation for routine changes, and tighter links between change and configuration data.
Which Framework Should You Follow?
Most teams use ITIL as their IT change management framework because its language (RFC, CAB, standard change) is widely understood. Teams under formal audit may also map their process to the change controls in ISO/IEC 27001 or COBIT. You do not need to pick one forever. Start with the ITIL change types and the 8 steps above, then add controls your auditors ask for. These ITIL best practices are a good next read.
FREE. All Features. FOREVER!
Try our Forever FREE account with all premium features!
IT vs. Organizational Change
IT change management controls changes to technology so services stay stable. Organizational change management helps people adopt new processes, roles, or tools. Release management packages and deploys groups of changes. They overlap during big rollouts, but each answers a different question.
| Dimension | IT change management | Organizational change management | Release management |
| Core question | Is this change safe to make? | Will people adopt this change? | How do we package and deploy it? |
| What changes | Systems, configurations, infrastructure | Behaviors, roles, processes | Bundles of software or configuration changes |
| Typical owner | IT manager or change manager | HR, project leaders, executives | Release or DevOps lead |
| Key artifacts | RFC, risk score, backout plan, change log | Communication plan, training, adoption metrics | Release plan, build notes, deployment schedule |
| Example | Updating email routing rules | Training staff on a new ticket submission process | Shipping version 2.3 of an internal app |
During a help desk switch, you need all three. IT change management protects the cutover weekend, release management handles the configuration bundle, and organizational change management gets employees to stop emailing the old address.
Change management also connects to problem management. When a problem investigation finds a root cause, the permanent fix usually becomes a change request. The ITIL problem management lifecycle shows where that handoff happens.
What Mistakes Should You Avoid?
The most damaging IT change management mistakes are building a process too heavy to follow, approving your own changes, skipping backout plans, and tracking changes in chat. Each one either pushes people around the process or leaves you without a record when something breaks.
Process gaps, not technical skill, are usually the weak spot. A study by Uptime Institute in 2025 found that nearly 40% of organizations had a major outage caused by human error over the previous three years. Of those incidents, 85% came from staff not following procedures or from flaws in the procedures themselves.
Copying an Enterprise Process
A 12-stage workflow designed for a bank will not survive contact with a four-person team. People start skipping steps, and the records you do have become unreliable. Instead, start with the three change types, one intake form, and risk-based approvals. Add steps only when a real failure shows you need them.
Treating Every Patch as a Normal Change
Sending each OS patch to a review meeting creates a backlog, and backlogged patches are a security risk of their own. Instead, pilot your monthly patch cycle on a small group, then run the rest as a standard change. Keep emergency patches on the emergency path with a review afterward.
Approving Your Own Changes
When the requester, implementer, and approver are the same person, nobody catches the assumption that turns into an outage. Instead, require a second person on every normal change, even if that review is a five-minute read of the ticket.
Skipping the Backout Plan
“We will restore from backup” is not a plan unless you know the backup works and how long a restore takes. Instead, write the exact rollback steps, test them when you can, and set a time limit that triggers them.
Tracking Changes in Chat or Email
Chat threads are great for coordination and terrible for history. Six months later, nobody can find who approved the firewall rule. Instead, keep one ticket per change and link any chat discussion to it.
Letting Emergency Changes Become the Default
If a large share of your changes are emergencies, people may be using that lane to avoid approvals. Instead, review every emergency change and track the emergency percentage as a metric.
What Are the Best Practices?
IT change management best practices for small teams focus on keeping the process light and the records reliable: maintain a standard change catalog, freeze changes around critical dates, pilot before full rollout, connect changes to incidents, and automate the routing and reminders instead of the judgment.
- Keep a living standard change catalog. Review it quarterly. Promote proven normal changes and demote any standard change that caused an incident.
- Publish a change freeze calendar. Block non-emergency changes around payroll, month-end close, open enrollment, audits, and your busiest sales or clinic weeks.
- Pilot first, then roll out. Test on one team, site, or queue before touching everyone. This single habit catches many configuration mistakes.
- Use templates for recurring changes. A prefilled request for “new integration” or “routing rule update” keeps quality high and saves time.
- Automate the paperwork, not the decision. Let your tool assign requests, notify approvers, and send reminders. Help desk automation handles that routing so people can focus on judging risk.
- Connect changes to incidents. When an incident follows a change, link them. Over time you will see which systems or change types fail most.
- Make runbooks easy to find. Store standard change procedures in a searchable knowledge base, such as ProProfs Knowledge Base, so any technician can run them the same way.
- Report monthly, briefly. Share a one-page summary of changes made, success rate, and emergency changes with leadership.
How Do Different Teams Use It?
Different teams apply the same IT change management process to different risks. Healthcare IT protects clinical and staff systems, HR and university teams protect payroll and records, managed service providers protect many client environments at once, and support teams in manufacturing or ecommerce protect the help desk automation customers rely on.
Healthcare and Medical IT Teams
Small hospital and medical services IT teams support employees around the clock, so timing matters as much as risk. Schedule changes away from shift handovers, categorize change records by area (desktop, applications, access), and report monthly to management. When two related companies share one IT desk, record which company each change affects. Teams evaluating tools can compare options in this guide to help desk software for healthcare.
Example: A printer driver update for nursing stations runs first on one unit for a week, then becomes a standard change for the rest of the building.
HR, Payroll, and University Service Teams
HR and payroll teams increasingly own system settings, such as benefits mailbox routing, form fields, or integrations with a student or HR information system. Treat changes to those settings as normal changes, freeze them around payroll runs and open enrollment, and add an escalation rule if an approval stalls. An HR ticketing system can host both the inquiries and the change records.
Managed Service Providers
MSPs make changes across many client tenants, sometimes in the same afternoon. Every change record needs the client name, the tenant or domain, and the client contact who approved it. Keep separate change windows per client, and send notices from the right client identity. This overview of an MSP ticketing system covers the multi-client setup.
Manufacturing and Ecommerce Support Teams
For customer-facing support teams, the riskiest changes are often inside the help desk itself. Switching assignment from round robin to least busy, changing a 31-day automated follow-up sequence, or connecting a store platform that sends order and shipping emails can all affect customers. Test new rules on a single queue first, and keep the old rule documented so you can switch back.
FREE. All Features. FOREVER!
Try our Forever FREE account with all premium features!
Which Metrics Should You Track?
Small teams should track change success rate, change failure rate, emergency change percentage, approval time, and review completion. Together, these show whether changes are safe, whether the process is followed, and whether it is fast enough that people do not bypass it.
| Metric | What it tells you | Healthy direction |
| Change success rate | Share of changes completed without rollback or incident | Up |
| Change failure rate | Share of changes that caused an incident or needed remediation, as defined in DORA’s metrics guide | Down |
| Emergency change percentage | How often the fast lane is used | Low and stable |
| Average approval time | Whether approvals are a bottleneck | Down, by risk level |
| Unauthorized changes found | Changes made without a record | Toward zero |
| Reviews completed | Share of normal and emergency changes reviewed before closing | Up |
Start with three: success rate, emergency percentage, and approval time. If you already track help desk metrics like response time, add these to the same monthly report.
What to Look for in Software?
Good IT change management software gives you one place to log change requests, route them to the right approver, track tasks and schedules, and keep an audit trail. Small teams should prioritize ease of use, email and form intake, custom fields, automation, and reporting over enterprise extras they will not use.
| Criterion | Why it matters | Question to ask in a demo |
| Simple intake | Changes only get logged if logging is easy | Can requests arrive by email and by form into one queue? |
| Custom fields and labels | You need to filter by change type, risk, and system | Can I make risk score and backout plan required fields? |
| Workflow automation | Routing and reminders keep approvals moving | Can it auto-assign by category and notify approvers? |
| Subtasks | Big changes involve several people | Can I split one change into tasks for different teams? |
| Internal notes and history | Approvals and decisions must be on the record | Are notes private, timestamped, and exportable? |
| Reporting | Leadership and auditors will ask for numbers | Can I report by custom field and export to a spreadsheet? |
| Integrations | Changes touch the tools you already use | Does it fit with Microsoft 365, single sign-on, and chat tools? |
| Hosting and access control | Server maintenance is a cost of its own | Is it cloud-hosted, with roles, permissions, and IP restrictions? |
| Pricing model | Ticket volume can swing month to month | Is pricing per user, so the bill stays predictable? |
Be honest about scale. If you run hundreds of changes a week, need a configuration management database (CMDB), or want approvals tied to automated deployment pipelines, a full ITSM suite is the better fit. This roundup of ITSM tools is a good place to compare them.
If your team already works out of a shared inbox, a help desk can carry most of this process. ProProfs Help Desk is the easiest AI help desk for shared inboxes, ticket workflow automation, and scaling support teams. You can build a change request form, tag requests by change type with custom fields and labels, split a migration into child tickets, keep approval decisions in private notes, and pull reports by custom field at month end.
Its AI ticket summarization condenses a long change thread into a short brief for the approver, and AI response suggestions help draft user notices faster.
It does not include a CMDB, so teams that track configuration items in detail should pair it with an asset tool or choose a dedicated ITSM suite. There is a free plan for a single agent, and paid plans are priced per user.
Track Every Change Request, Approval Note, and Review in One Shared Inbox
Make Every IT Change a Safe One
IT change management comes down to one habit: every change gets a record, a risk check, the right approver, a way back, and a review. The 8 steps in this guide turn that habit into a workflow you can run with a small team and the tools you already have.
If you are just starting, focus on three things first: one intake form, a risk score that decides who approves, and a written backout plan for anything above low risk. Once those stick, add a standard change catalog and a monthly metrics review.
If your requests already land in a shared inbox, ProProfs Help Desk can hold the whole process in one place, from the request form to the final review. Start small, measure what happens, and let the process grow only as fast as your team needs it to.
Give Your It Team a Change Log That Answers “What Changed?” in Seconds
Frequently Asked Questions
Does a Small IT Team Need a Change Advisory Board?
No. Most small teams do well with a named approver for each risk level and a second-person rule for normal changes. Bring two or three people together, in a short call or ticket thread, only for high-risk or cross-department changes.
Is IT Change Management the Same as Change Control?
In practice, yes. Both describe the same discipline of reviewing and authorizing IT changes. Some teams use "change control" for the approval step only. ITIL 4 briefly used "change control" before renaming the practice "change enablement."
Do Security Patches Need to Go Through Change Management?
Yes, but most should not need individual approval. Pilot routine patch cycles on a small group, then run them as a standard change. Treat patches for actively exploited vulnerabilities as emergency changes and review them afterward.
How Long Should a Change Approval Take?
Approval time should match risk. Standard changes need none, low-risk normal changes can be approved the same day, and high-risk changes may take a few business days. If approvals routinely take a week, people will start working around the process.
What Is a Backout Plan?
A backout plan is the written set of steps to return a system to its previous state if a change fails. A good one names the exact actions, who performs them, how long they take, and the condition that triggers them.
What Is a Change Freeze?
A change freeze is a period when only emergency changes are allowed. Teams set freezes around high-risk business dates, such as payroll runs, month-end close, open enrollment, major go-lives, or peak sales weeks, to reduce the chance of disruption.
Is IT Change Management Required for Compliance?
Often, yes. Security standards such as ISO/IEC 27001 include change management controls, and auditors who review IT general controls typically test change records. Even without a formal mandate, a clean change log makes audits and security reviews much faster.
Can You Run Change Management in a Help Desk?
Yes, for most small and mid-sized teams. A help desk with custom ticket forms, labels, child tickets, private notes, and reports can host requests, approvals, and reviews. Move to a full ITSM suite when you need a CMDB or pipeline-driven approvals.
FREE. All Features. FOREVER!
Try our Forever FREE account with all premium features!

 We'd love your feedback!
What did you like & how can we make it even better?
 Thanks for your feedback!
 Ask Your Question
Have a question? Get expert help to make your decision easier.